Webhook and Post-Back Options for Call Event Data
Webhook and post-back options for call event data let you push calls into internal systems in real time. Call (510)-663-7016 for integration guidance.
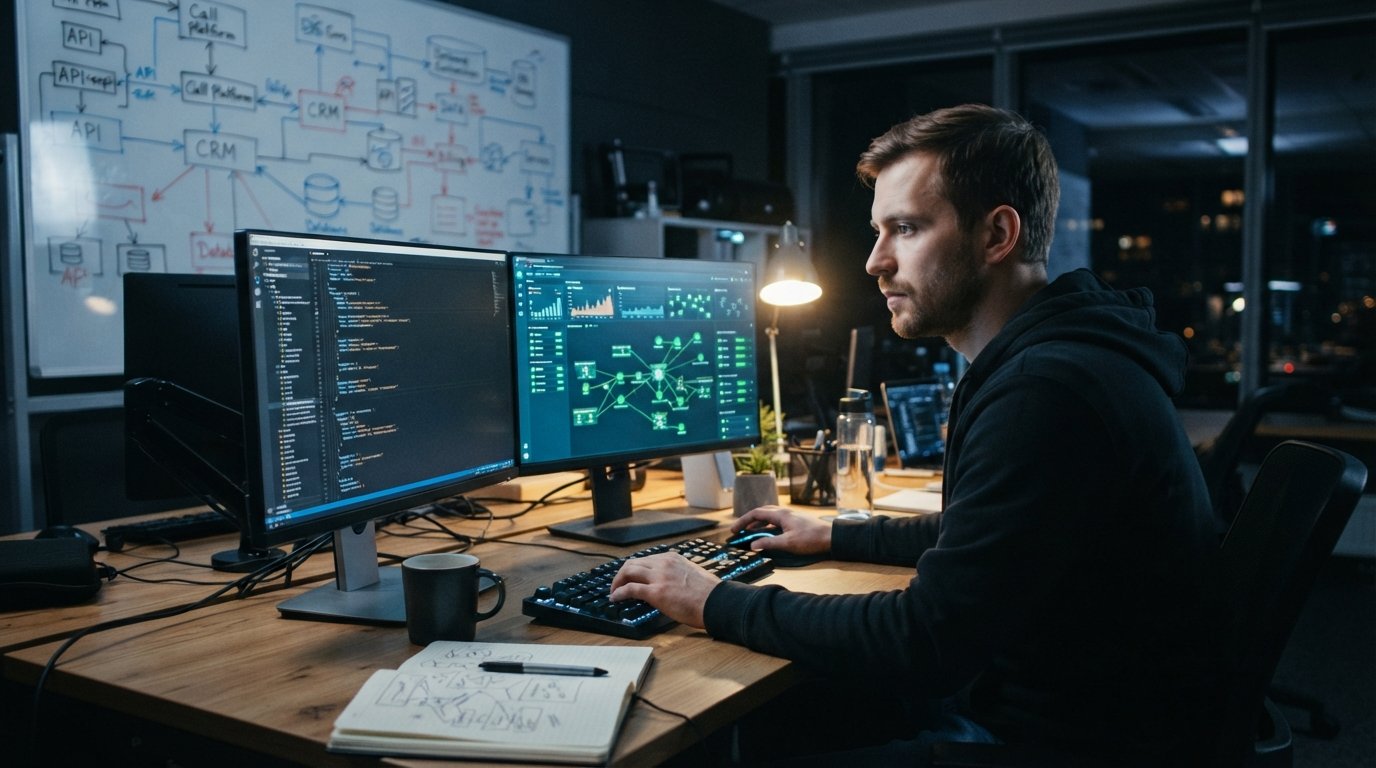
Your call platform already knows the moment a caller connects, qualifies, or converts. The question is how fast that knowledge reaches the systems that need it. If your team still exports CSVs or polls a reporting API every fifteen minutes, you are reacting to yesterday's revenue while it happens. Webhook and post-back options for call event data close that gap: the platform pushes each event to your endpoint the instant it occurs, so your CRM, bidding engine, and billing ledger stay in sync without manual pulls.
This guide is written for the engineer or technical marketer who owns that integration. It covers which call events are worth sending, how to shape a payload that downstream systems can consume without rework, how to handle retries and failures so nothing slips through, how to secure the endpoint, and how to reconcile pushed events against platform reporting. Pay-per-call platforms like PayPerCall Marketing expose webhooks precisely for this purpose, and the design decisions below apply whether you build on their stack or another. If you are also tightening up your call supply, our guide on proactive fraud prevention controls for pay per call advertisers pairs well with the event-driven approach described here.
Why Push Beats Pull for Call Event Data
Polling a reporting endpoint is the default pattern because it is easy to reason about: you ask, you receive, you repeat. But polling has structural costs. It introduces latency equal to your polling interval, it wastes API quota on unchanged data, and it forces you to build stateful pagination logic to avoid missing records between requests. In a pay-per-call operation where a qualified call can trigger a bid adjustment, a routing change, or a billing event, fifteen minutes of lag is a business problem, not a technical detail.
Webhooks invert the model. The platform becomes the producer and your system becomes the consumer. Each call event fires once, at the moment of truth, and is delivered to a URL you control. That gives you real-time reaction: a disposition of "qualified" can update a CRM within seconds, a failed call can trigger a courtesy follow-up, and a suspicious pattern can pause a publisher before the next call arrives. Post-backs are the same concept with a narrower contract, typically a server-to-server ping with minimal fields, often used for conversion confirmations or affiliate payout triggers.
The tradeoff is that push shifts reliability responsibility to you. A webhook that fails silently is worse than a poll that always returns, because you may not notice the gap until reconciliation. The rest of this article is about earning the real-time benefit without inheriting that risk.
Which Call Events Are Worth Sending
Not every state change in a call deserves a webhook. Sending too much creates noise, increases endpoint load, and makes it harder to distinguish signal from routine. The right event set depends on what downstream systems actually do with the data, but four categories cover most pay-per-call integrations.
- Call start (ring or connect): fires when the call is initiated or answered. Useful for real-time dashboards, capacity planning, and pre-call routing decisions. This is the highest-volume event, so treat it as optional unless you have a genuine real-time need.
- Call completion: fires when the call ends, with duration, outcome, and recording reference. This is the workhorse event for CRM logging, billing, and attribution.
- Qualification: fires when the call passes or fails your quality criteria (IVR answers, minimum duration, geography, business hours). This is the event that should drive payout and bidding logic, because it is the one that maps to money.
- Disposition: fires when an agent or automated system assigns a final status such as sale, not interested, callback requested, or invalid. Dispositions often arrive after the call ends, sometimes hours later, so they need their own event and their own idempotency key.
A practical starting point is to subscribe only to qualification and disposition events, add completion once your CRM pipeline is stable, and leave start events for a later phase. Each event should carry a stable event ID and a call ID so consumers can deduplicate and join records across event types. If your platform lets you filter subscriptions by campaign or publisher, use that: fewer irrelevant events means fewer failure modes.
Designing a Payload Downstream Systems Can Consume
Most integration pain comes from payloads that force the consumer to make a second API call to get the data it actually needs. A well-designed call event payload is self-contained: everything required to act on the event is in the body, with identifiers included for optional enrichment. Design it once, version it, and resist the urge to bolt on fields without a schema change.
At minimum, every event should include an event ID, event type, timestamp in ISO 8601 with timezone, call ID, campaign ID, publisher or source ID, caller phone number (hashed or masked if your compliance posture requires it), call duration, and the qualification or disposition outcome. Add a signature header and a schema version so consumers can validate and evolve independently. For post-backs, keep the body minimal (call ID, status, payout amount, timestamp) and put everything else behind an authenticated lookup endpoint.
Two design choices pay for themselves quickly. First, use a consistent envelope across event types: same top-level keys, same timestamp format, same ID conventions. Second, make events immutable and append-only. If a disposition changes, emit a new event with the same call ID and a later timestamp rather than mutating the original. Consumers can then rebuild state by replaying events, which is invaluable during incident recovery. Document the schema in a shared contract (OpenAPI or JSON Schema) and treat breaking changes as versioned releases, not silent edits.
Retry and Failure Handling So Missed Events Do Not Become Lost Revenue
Webhook delivery fails. Endpoints time out, deploy windows drop connections, and DNS has bad days. The platform should retry with exponential backoff, but you cannot assume any specific retry policy, so your consumer must be idempotent and your operations must include a reconciliation loop. The goal is at-least-once delivery with exactly-once processing on your side.
- Acknowledge fast, process asynchronously. Return a 2xx response as soon as the payload is durably queued (for example, written to a message queue or a staging table). Do not do heavy processing inside the request handler; slow handlers cause retries and duplicate work.
- Deduplicate by event ID. Store processed event IDs with a TTL at least as long as the maximum retry window. If an event arrives twice, the second delivery is a no-op.
- Use a dead-letter queue. After a defined number of failed processing attempts, move the event to a dead-letter queue with the full payload and error context. Alert on queue depth so failures surface in minutes, not at month-end.
- Run a daily reconciliation job. Pull the platform's reporting totals for the previous day and compare counts and amounts against your processed events. Any delta is a signal to replay from the dead-letter queue or request a report backfill.
Retry semantics deserve a explicit contract with the platform. Ask whether failed deliveries retry automatically, for how long, and whether you can trigger a manual replay for a time window. PayPerCall Marketing's reporting and analytics tooling gives you the source-of-truth numbers you need for reconciliation, and its call tracking layer provides the call-level detail to match against. Build the reconciliation job before you go live, not after the first missed event.
Security Considerations for Endpoints Receiving Call Data
Call event payloads contain personal data: phone numbers, call outcomes, sometimes recordings. An endpoint that accepts them is an attack surface, and treating it casually is how leaks happen. Four controls are non-negotiable.
- Verify signatures. Require an HMAC signature header computed over the raw request body with a shared secret, and reject requests that fail verification. Compare in constant time to avoid timing leaks.
- Enforce TLS and allowlist. Accept only HTTPS, and where the platform supports it, restrict delivery to known source IP ranges. Reject plain HTTP outright.
- Minimize and mask. Store only the fields you need. Hash or mask caller numbers at ingestion if downstream systems do not require the raw value, and never log full payloads containing personal data.
- Rotate secrets and audit access. Support at least two active signing secrets so you can rotate without downtime, and log every delivery attempt with source IP and verification result for audit purposes.
Also consider replay protection: include a timestamp in the signed payload and reject events older than a defined window. This prevents an attacker who captures a valid request from replaying it later. None of these controls is exotic, but each one is easy to skip under deadline pressure, and each one matters more as call volume grows.
Reconciling Pushed Events With Platform Reporting
Webhooks tell you what happened; reporting tells you what the platform recorded. The two should agree, and when they do not, you want to know within a day, not a quarter. Reconciliation is the discipline that keeps an event-driven integration honest.
Start with a daily job that pulls aggregate counts and amounts per campaign and publisher from the platform's reporting API, then compares them to your processed event totals for the same period. Track three metrics: event count delta, qualified-call delta, and payout-amount delta. A small delta from late-arriving dispositions is normal; a persistent delta in one direction usually means dropped deliveries, a subscription misconfiguration, or a schema change that broke parsing. Route each delta to an owner and a runbook step, whether that is replaying from the dead-letter queue or requesting a backfill.
Keep the reconciliation window aligned with your payout cycle. If publishers are paid weekly, reconcile weekly at minimum and daily if volume justifies it. Store the raw payloads (or a redacted hash) for the same period so you can investigate discrepancies without depending on the platform's retention. Over time, this dataset becomes your best defense in payout disputes and your best input for fraud review, which is why platforms like Astoria Company's performance marketing platform emphasize transparent reporting alongside their call tracking and fraud prevention tooling.
Putting It Together: A Practical Rollout Sequence
A webhook integration does not need to be a big-bang project. Sequence it so each phase delivers value and each phase is testable in isolation.
- Define the event contract: event types, envelope fields, schema version, and signature scheme.
- Stand up a staging endpoint with signature verification, idempotency storage, and a queue in front of processing.
- Subscribe to qualification events only, and wire them into a single downstream system (your CRM or billing ledger) to prove the path end to end.
- Add disposition and completion events, then build the dead-letter queue and alerting.
- Launch the daily reconciliation job and run it in shadow mode for a week before trusting it.
- Expand to additional consumers (bidding, routing, dashboards) only after the first path is stable.
Each step is small enough to review and roll back. The sequence also front-loads the controls that prevent silent failure, which is the failure mode that costs money in pay-per-call. Real-time event data is only valuable if you can trust it, and trust comes from verification, idempotency, and reconciliation working together.
Webhook and post-back options for call event data turn your call platform from a reporting tool into a live signal source. Choose events that map to money, design a self-contained payload, assume delivery will fail and build for it, secure the endpoint like the personal-data surface it is, and reconcile against platform reporting every day. Do those five things and your downstream systems will see every call as it happens, with no gaps to explain at month-end.